


Public release. SERV Reasoning is available to everyone. Create an account →
Why SERV Reasoning
Better outputs
Every request runs through a reasoning step, so outputs are more accurate and consistent than calling the model directly.
Lower cost
Pair a smaller model with SERV Reasoning to reach a larger model’s quality. Savings scale with volume.
No code changes
Change the base URL and API key in your existing OpenAI or Anthropic SDK. Requests must include a system prompt and use a model the endpoint serves; see endpoint compatibility.
One endpoint, many models
A broad catalog of models behind a single endpoint and a single API key.
Try before you integrate
Compare any model with and without SERV Reasoning in the Playground. No code required.
SERV Tools
The three features below are SERV Tools. Turn each one on or off per request by adding its tool to the request, in any SDK.Prompt injection guard
Protect your system prompt from injection-based leakage. Opt in with the
serv_prompt_guard tool.Reasoning-prompt content filter
On by default for Chat Completions and Responses: SERV blocks output that copies its generated reasoning prompt. Disable it per request with the
serv_disable_content_filter tool.Shadow agents
Difficult tasks reach higher accuracy through a validate-and-iterate loop. Opt in with the
serv_shadow_agent tool.How it works
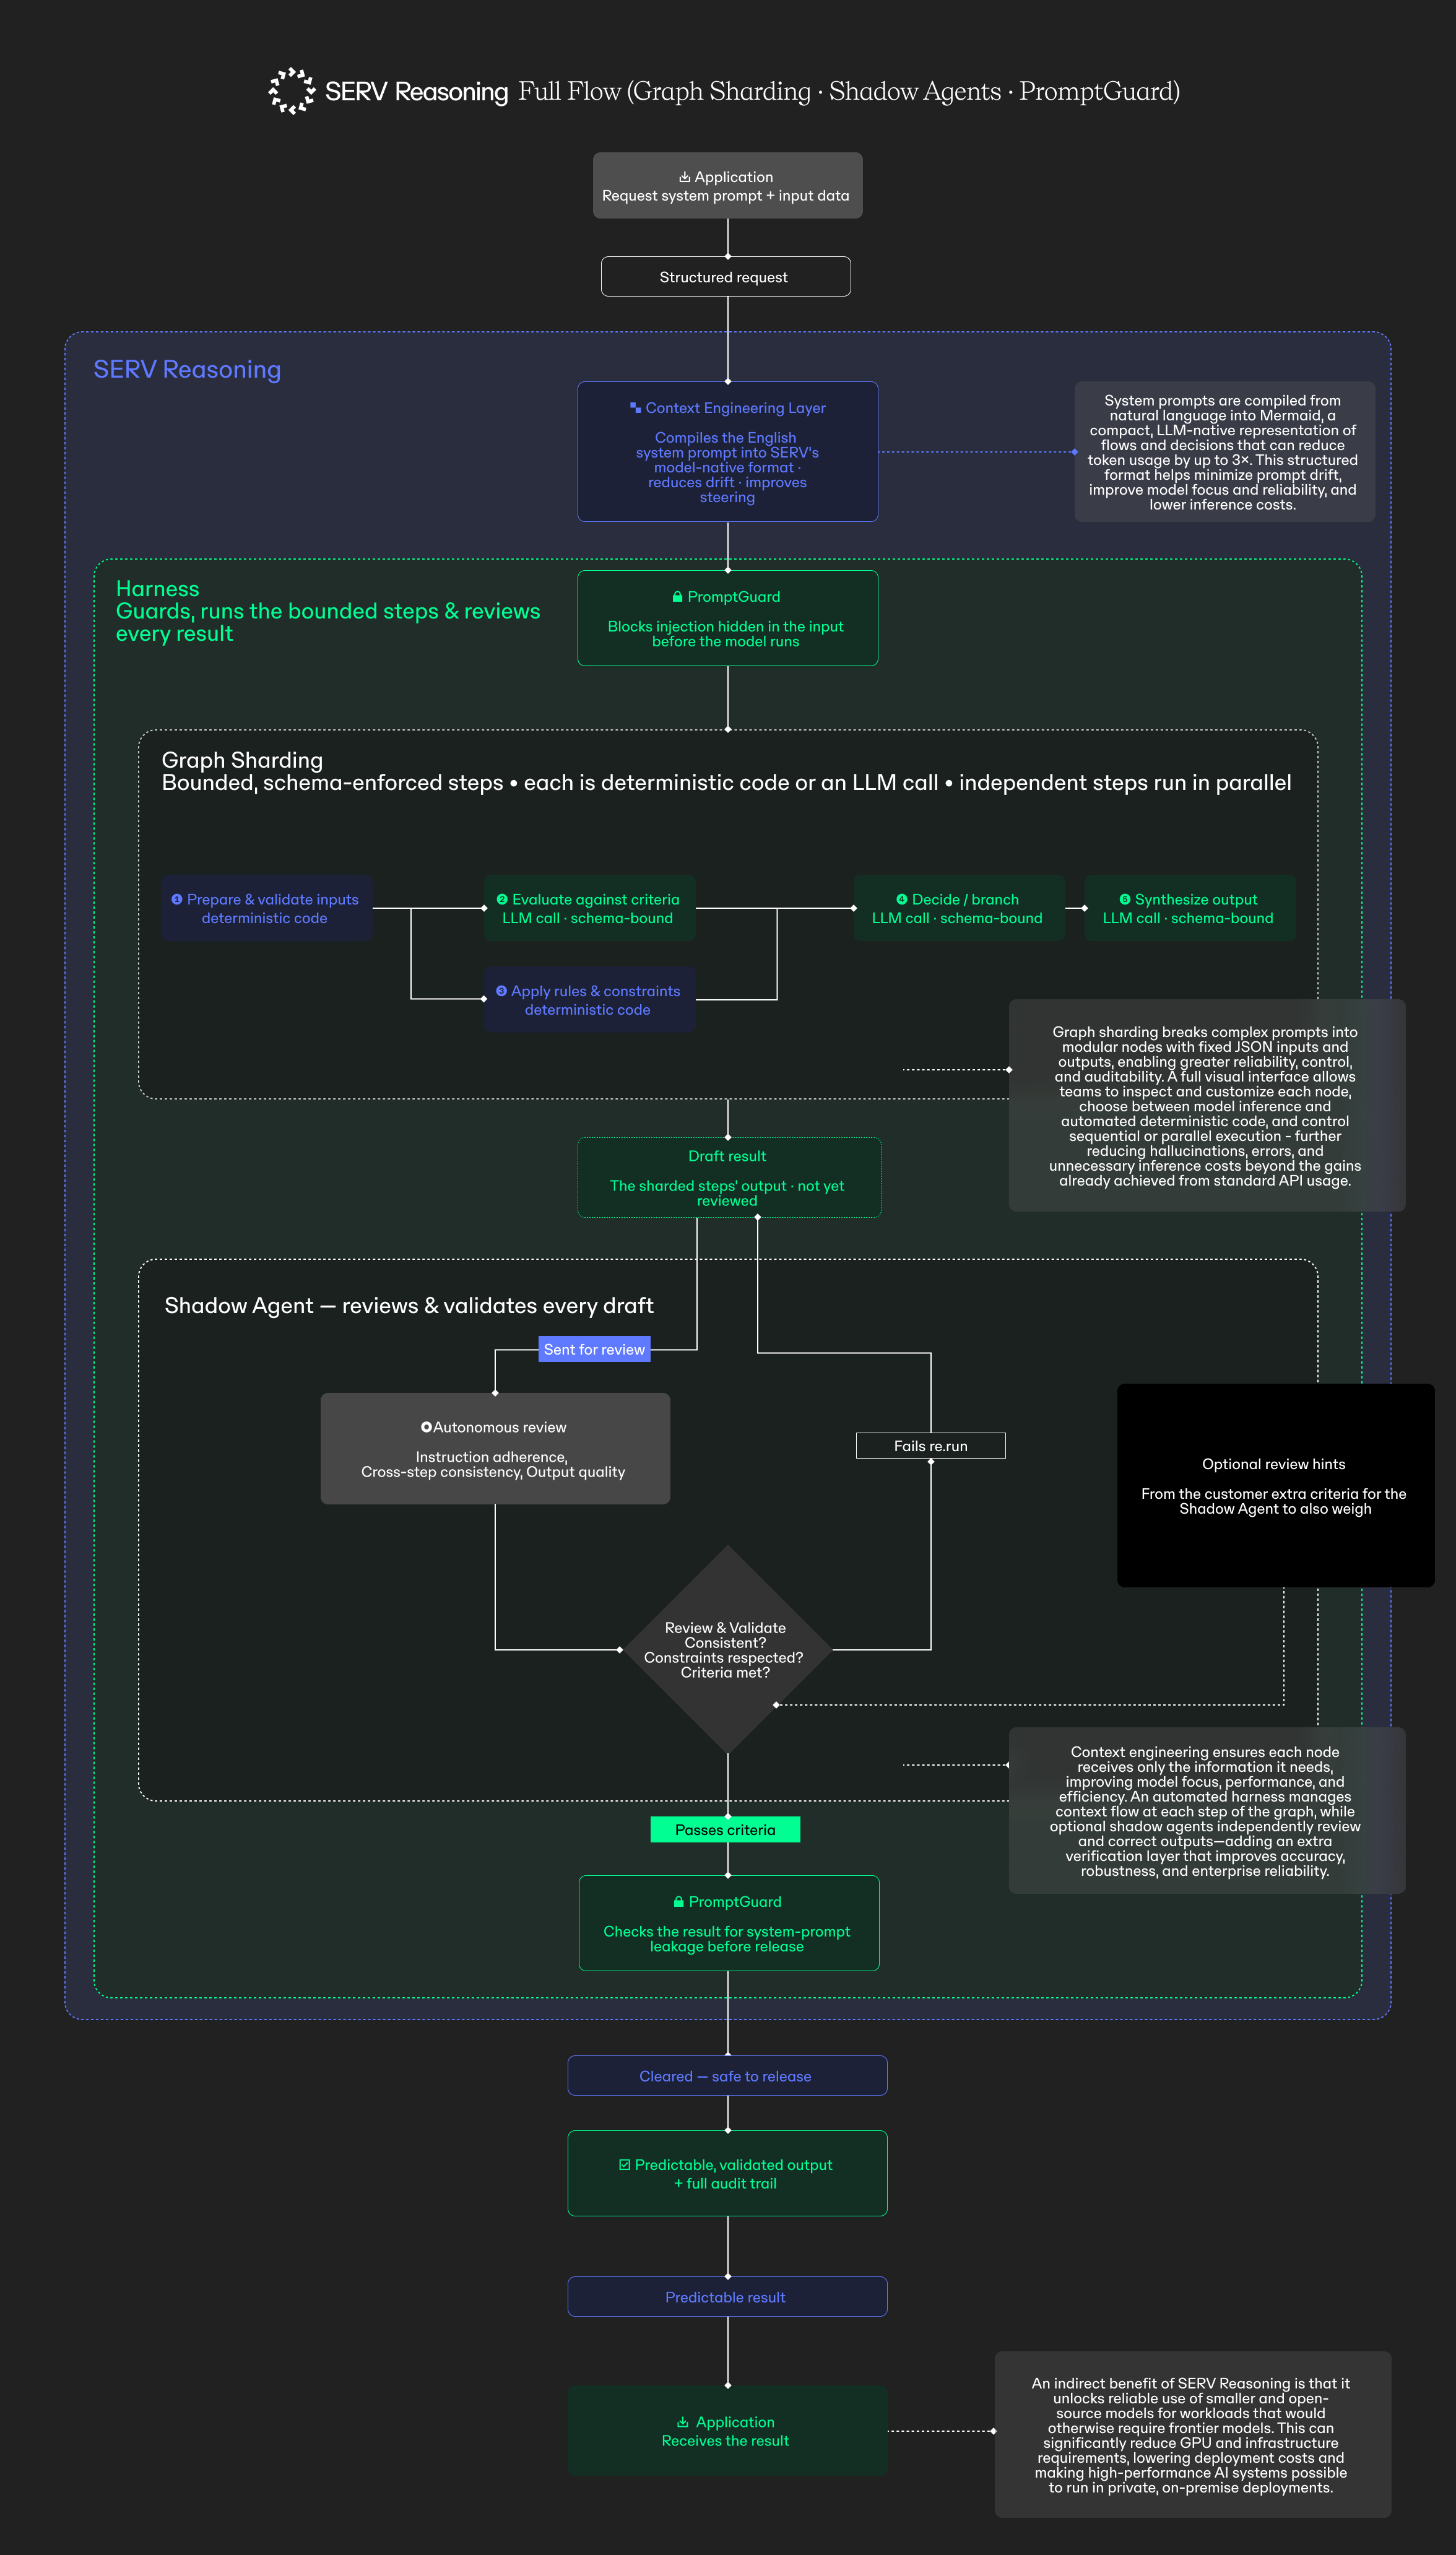
Full technical diagram of SERV Reasoning engine: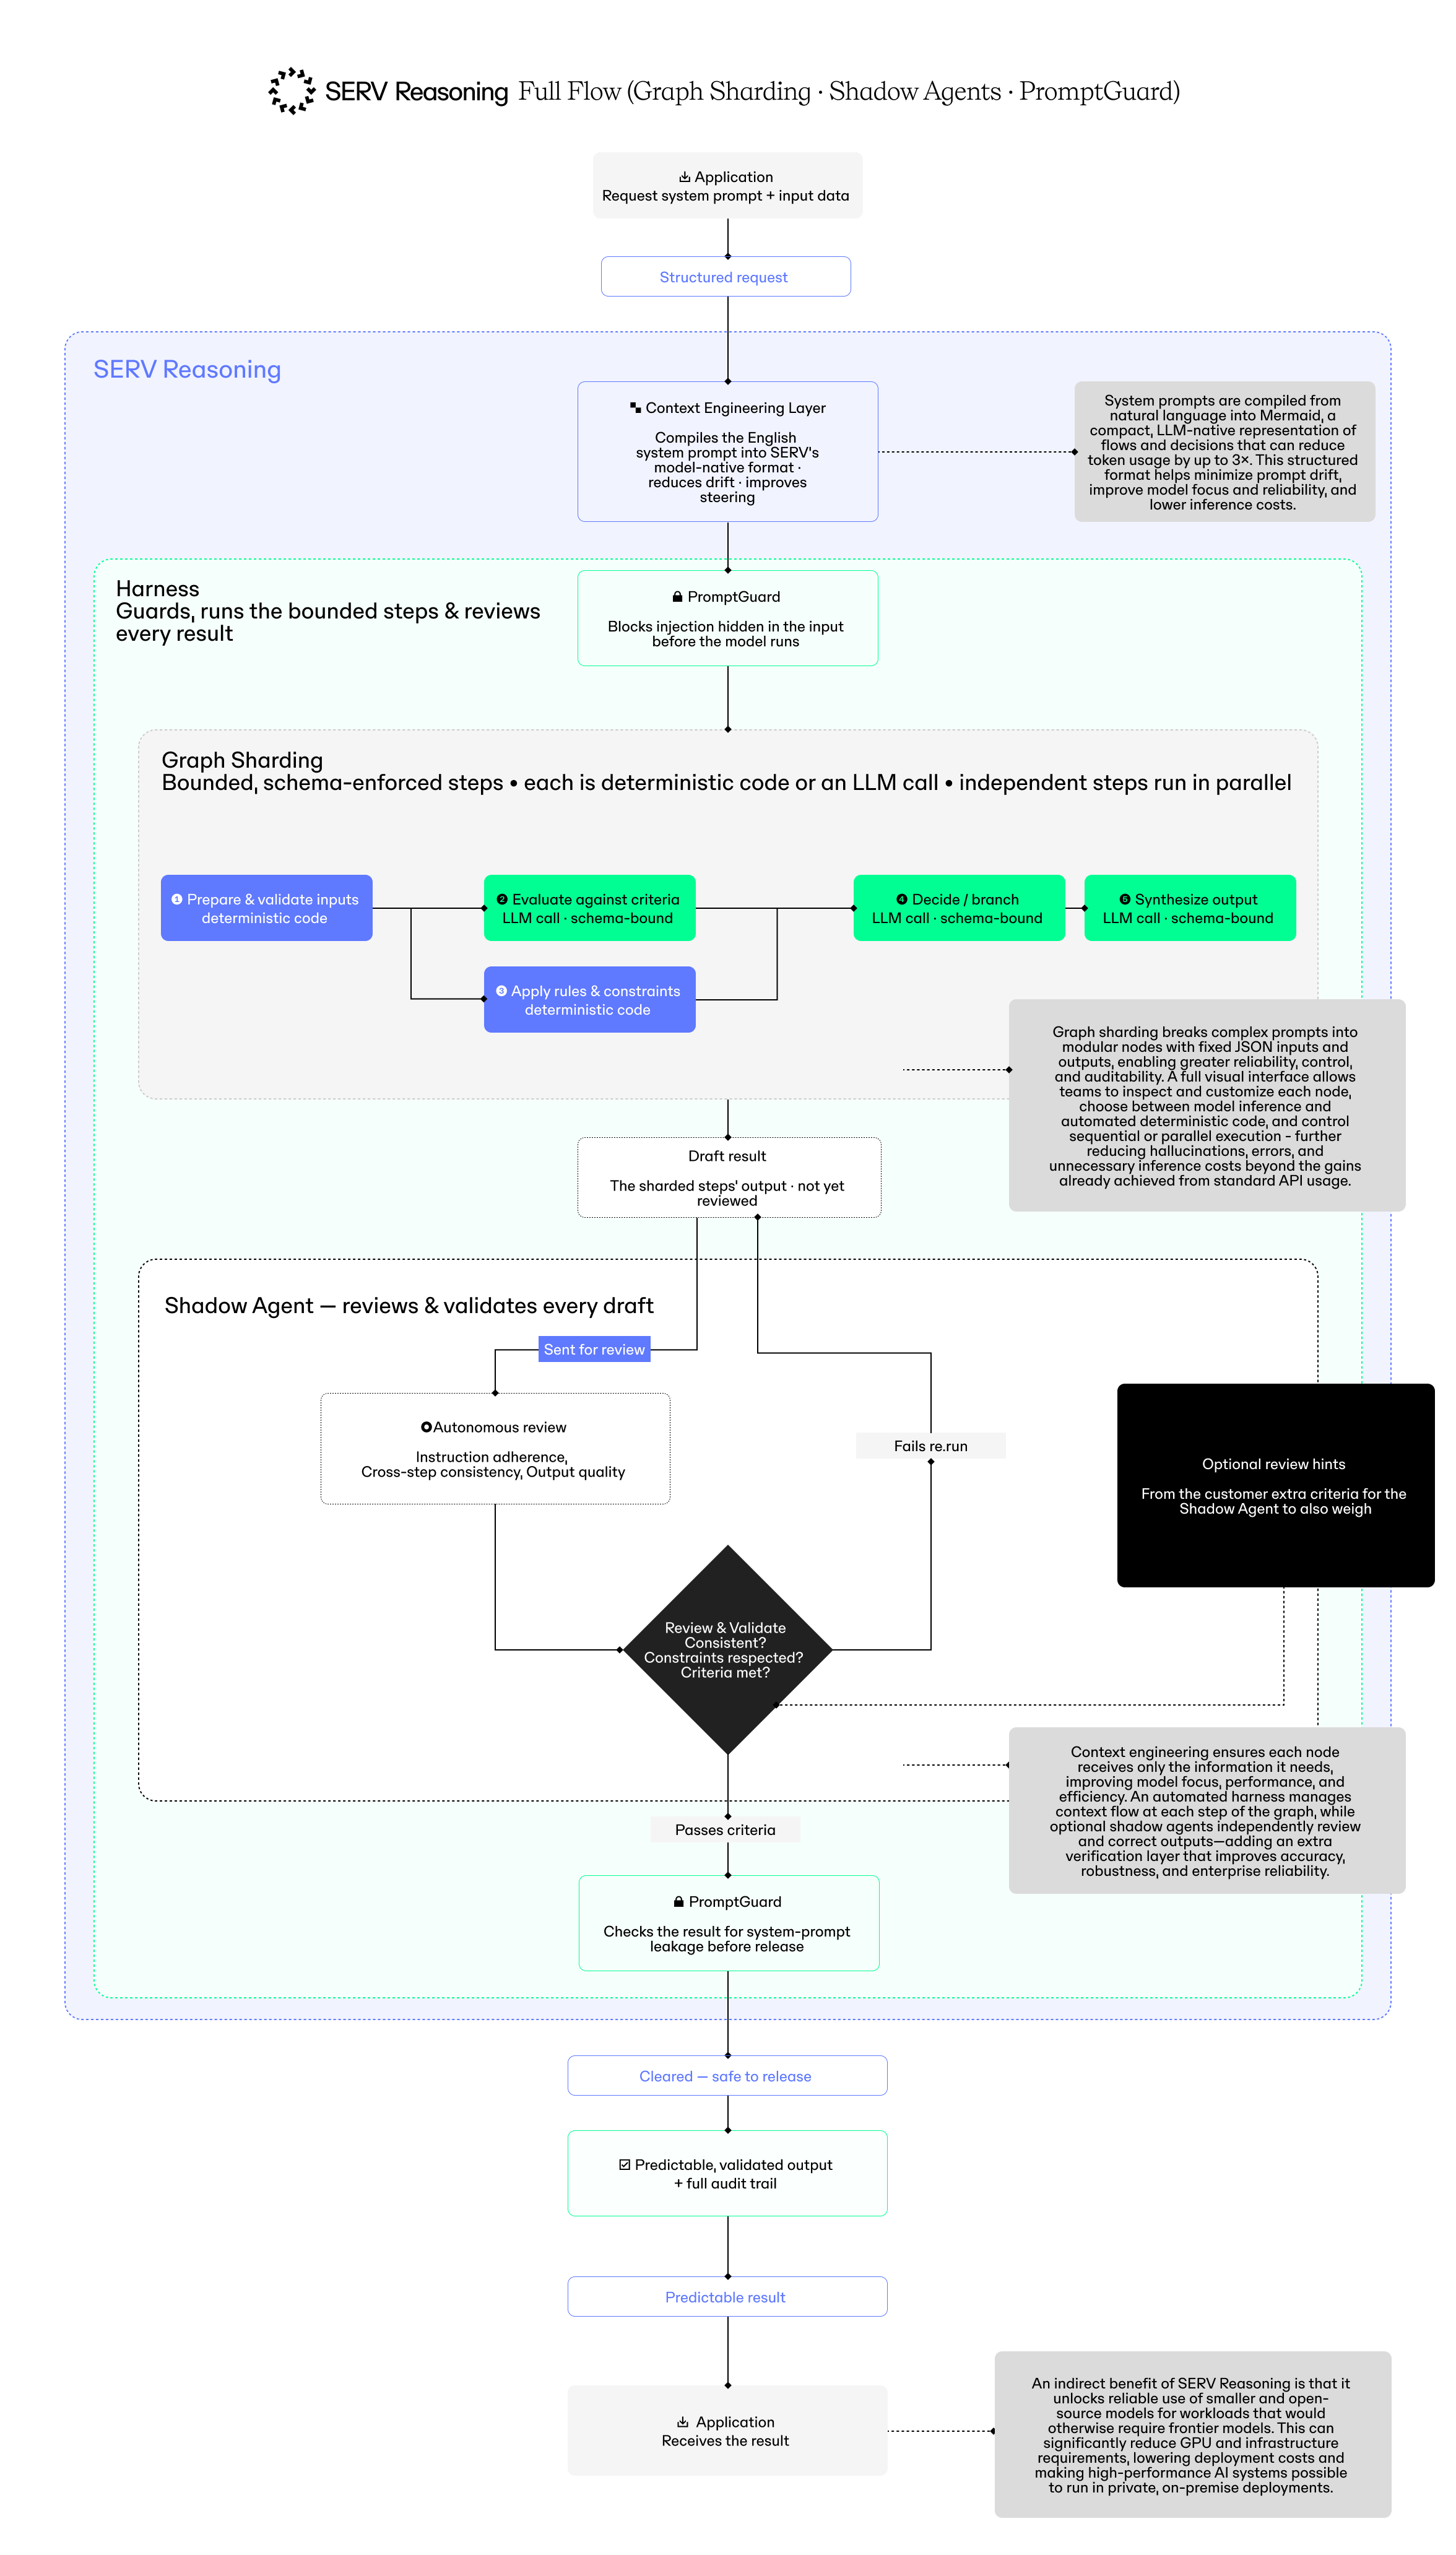
Next steps
Quickstart
Two-field SDK setup and the behaviors to know before you build.
Models
The full model catalog with pricing and context windows.
SDK Integration
Endpoint details and the parameter map for the OpenAI and Anthropic Node SDKs.
SDK Migration
Migration patterns for Python, Vercel AI SDK, LangChain, and raw fetch.